1
posts
2
3
4
YSK that uTorrent is a corporate spyware. It gathers your data without your consent. qBittorrent has no ads and gathers no data.
(thelemmy.club)
Don't use uTorrent. It's a scam.

5
6
YSK about the availability heuristic and how it affects our understanding of the world.
(lemmy.world)
The availability heuristic is a cognitive shortcut where people judge how common, likely, or important something is based on how easily examples of it come to mind, rather than how frequently it actually occurs.
Keep in mind, the media reports unusual events, and remember the old adage, "If it bleeds, it leads." This effect is compounded when we hear the same story from various sources and media types or a single event kicks of coverage of less serious but similar events.
US examples:
FOOD RECALLS
There's a widespread belief that federal cuts have led to an unsafe food supply and that recalls have skyrocketed. Weirdly enough, 2026 is on track to be a normal year for recalls, maybe even low.
The cyclospora outbreak, which was damned bad, was largely a result of a diminished CDC's ability to track the origin and spread. That was a result of staffing and budget cuts. While this event was going on, every single food recall made the news. 2026 seems unprecedented!
Keep in mind, 99% of food recalls are voluntary (this from several sources), initiated by the producer, nothing to do with the government. Producers have skin in the game. They don't want to get sued or see their stock tank, let alone have the feds twist their booty up like a balloon animal. The remainder are a result of the FDA and the FSIS doing their job. Also, keep on eye on the amounts involved. Most are less than a single semi truckload.
AIRLINE SAFETY
After Boeing lost a door over Portland, there were daily stories about airplane issues. Every tiny event was breathlessly reported, especially if it involved a Boeing plane. Absurdly enough, reports at the time would slip a sentence in near the end of the story saying "this wasn't a Boeing plane BTW".
Boeing has no doubt pulled some serious safety blunders, but neither that company, nor the industry as a whole, suddenly became unsafe, but you wouldn't know that if you followed the news in early 2024.
TRAIN SAFETY
After the disastrous derailment in East Palestine Ohio, it seemed trains were flying off the tracks daily. AH! And once again, daily reporting bent our opinion on a thing that's actually common and usually not a big deal. After the hype wore off, well, when was the last time you read a story about a derailment? You could have read one every day in early 2023.
FRIVOLOUS LAWSUITS
The media doesn't report the millions of meritorious lawsuits. They don't report cases thrown out by judges, and they can't report those that don't make it past an initial attorney consult.
Lawyers have to work with the same judges for years, maybe a whole career. The last thing they want is to antagonize them with BS. On top of that, attorneys don't want a loss on their record or a hit to their reputation.
One other note, some seemingly frivolous suits actually have legal merit, but the headlines only state the absurd part. Read the whole story. Anyone up for some McDonald's coffee?
GETTING SHOT/MASS SHOOTINGS
Americans and foreigners both think it's common to get shot in the US. The CDC puts yearly vehicular fatalities at the same number, give or take, as gun fatalities (50,000). So the odds are the same, right? Overall, yes. In reality? Not quite. The better question would be, are you more likely to die by gunshot or car crash?
Well over half of gun fatalities are suicides. Not to downplay those deaths! But they are not random events. Most of the rest is gang related activity. And again, not to downplay real deaths, but the vast majority of those are not random either.
Consider two scenarios:
A man goes nuts, kills his wife and two children, them himself. That makes national headlines, sometimes over a few days.
A family of 4 gets smeared off the interstate. Maybe a blurb in the local news, reported once and done.
But aren't mass shootings a daily event? Nope. While way too damned common, the scene in our head when we hear the term rarely matches the reporting of total numbers. This chart spells it out better than I can.

Quite a disparity! Note the sources. The three on the left are anything but right-wing.
The availability heuristic applies to school shootings as well; you'll hear about every event. Some sources count any time a gun is discharged on school grounds. If I put in round in the soccer field at midnight on Saturday, "school shooting". You'll find the same sorts of disparity as the mass shooting chart. You'll find yet another disparity looking into the most common cause of childhood deaths. (One wonders why sources include 18 and 19 year olds. Lock up your guns and teach your kids to swim, no worries.)
TO CLOSE
Examine your biases regularly. Check multiple sources, check past numbers vs. what you're seeing in the media. Read the whole story!
Random, horrible events make news, not common events, even if horrible. Yet sometimes common events can be blown up by reporting of a large initial event.
Don't fall into social media hype. Over on Bluesky they have a completely different set of concerns about current events than lemmy because once a thing takes off, it gets amplified in a given space. I've often seen an item get reported several times in short order and thought, "Oh boy, here goes this week's hype."
For those inclined to really unpack this thing, here's the paper that kicked off the idea of the availability heuristic:
https://cebma.org/assets/Uploads/Tversky_Kahneman_1974.pdf
Haven't read it all myself, but it's a banger so far!
7
8
You can login to (using my preferences as an example) DDG and configure it to not use AI, but I mostly browse in private/incognito mode and don't care to login to DDG every time I open a browser. However, I - and you - don't have to login to enforce that preference; at least with DDG you can set a default search engine that automatically avoids it. Here are the parameters in mobile Firefox:

Even in Chrome and Chrome derivatives, you can set a default search engine; I don't know the exact steps, but the end result should look similar to the above.
If you prefer to stick with Google, even they offer a no AI solution. I haven't used Google in years, but according to arstechnica, this would be the equivalent configuration:

I've not used any other search engines since Altavista, so I can't provide details for each one, but hopefully this is a good starting point.
edit: It seems this changed ... Or maybe I had it wrong from the beginning, but I tested this when I posted it, so I think it changed. Regardless, the q= is not necessary currently.

9
10
11
Crossposted from https://ibbit.at/post/128870

The basic concept of human intelligence entails self-awareness alongside the ability to reason and apply logic to one’s actions and daily life. Despite the very fuzzy definition of ‘human intelligence‘, and despite many aspects of said human intelligence (HI) also being observed among other animals, like crows and orcas, humans over the ages have always known that their brains are more special than those of other animals.
Currently the Cattell-Horn-Carroll (CHC) theory of intelligence is the most widely accepted model, defining distinct types of abilities that range from memory and processing speed to reasoning ability. While admittedly not perfect, it gives us a baseline to work with when we think of the term ‘intelligence’, whether biological or artificial.
This raises the question of how in the context of artificial intelligence (AI) the CHC model translate to the technologies which we see in use today. When can we expect to subject an artificial intelligence entity to an IQ test and have it handily outperform a human on all metrics?
Types Of Intelligence
While the basic CHC model contains ten items, the full model is even more expansive, as can be seen in the graphic below. Most important are the overarching categories and the reasoning for the individual items in them, as detailed in the 2014 paper by Flanagan and McGrew. Of these, reasoning (Gf, for fluid intelligence), acquired knowledge and memory (long and short term) are arguably the most relevant when it comes to ‘general intelligence’.
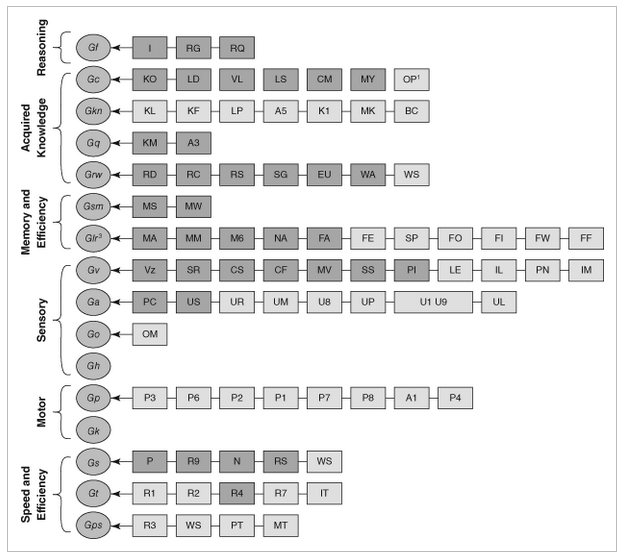
Current and expanded CHC theory of cognitive abilities. Source: Flanagan & McGrew (1997).
Fluid intelligence (Gf), or reasoning, entails the ability to discover the nature of the problem or construction, to use a provided context to fill in the subsequent steps, and to handle abstract concepts like mathematics. Crystallized intelligence (Gc) can be condensed to ‘basic skills’ and general knowledge, including the ability to communicate with others using a natural language.
The basic memory abilities pertain to short-term (Gsm) and long-term recall (Glr) abilities, in particular attention span, working memory and the ability to recall long-term memories and associations within these memories.
Beyond these basic types of intelligence and abilities we can see that many more are defined, but these mostly expand on these basic four, such as visual memory (Gv), various visual tasks, speed of memory operations, reaction time, reading and writing skills and various domain specific knowledge abilities. Thus it makes sense to initially limit evaluating both HI and AI within this constrained framework.
Are Humans Intelligent?
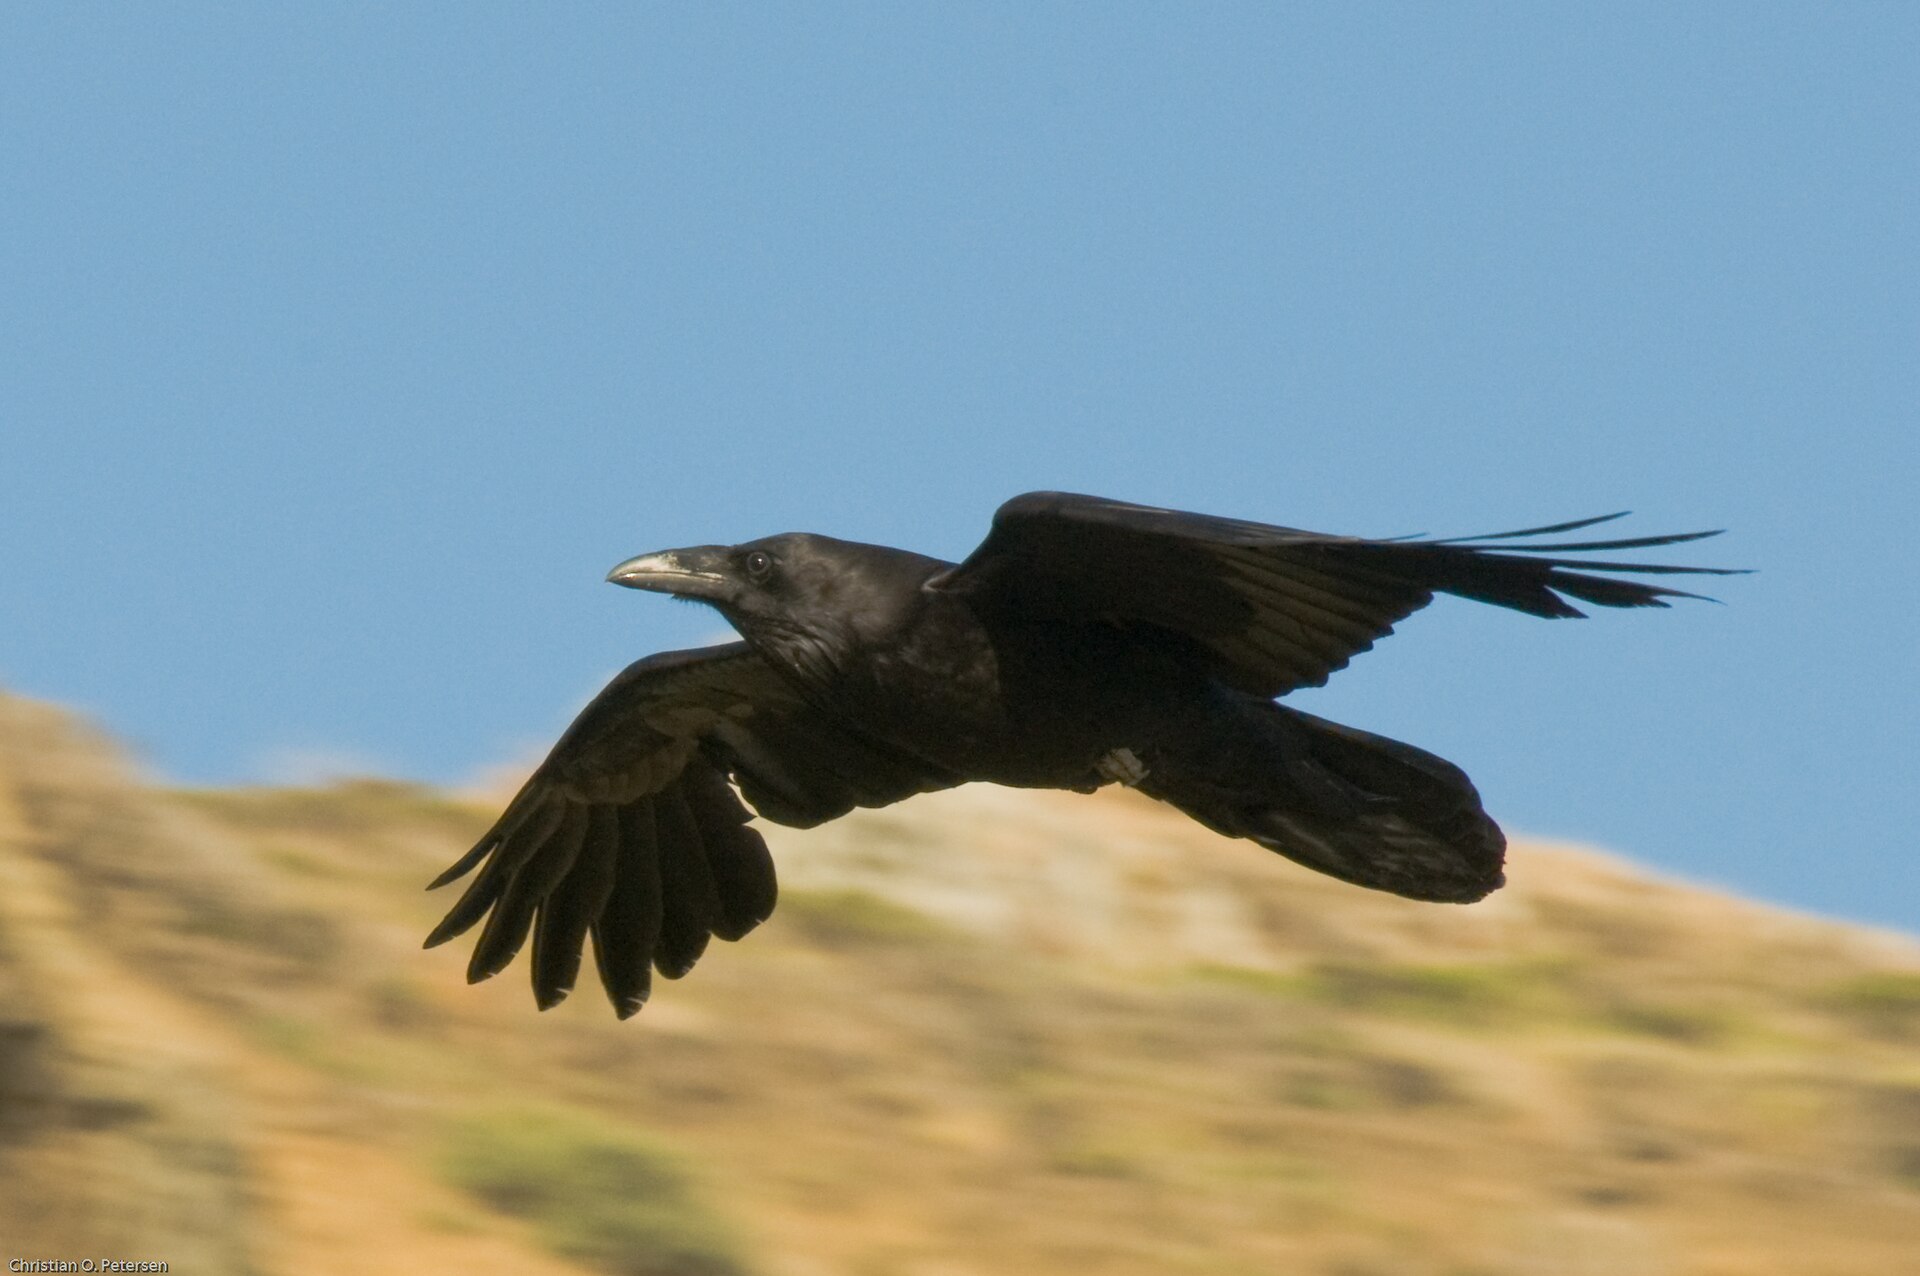
North American Common Raven (Corvus corax principalis) in flight at Muir Beach in Northern California (Credit: Copetersen)

It’s generally considered a foregone conclusion that because humans as a species possesses intelligence, ergo facto every human being possesses HI. However, within the CHC model there is a lot of wriggle room to tone down this simplification. A big part of IQ tests is to test these these specific forms of intelligence and skills, after all, creating a mosaic that’s then boringly reduced to a much less meaningful number.
The main discovery over the past decades is that the human brain is far less exceptional than we had assumed. For example crows and their fellow corvids easily keep up with humans in a range of skills and abilities. As far as fluid intelligence is concerned, they clearly display inductive and sequential reasoning, as they can solve puzzles and create tools on the spot. Similarly, corvids regularly display the ability to count and estimate volumes, demonstrating quantitative reasoning. They have regularly demonstrated understanding water volume, density of objects and the relation between these.
In Japanese parks, crows have been spotted manipulating the public faucets for drinking and bathing, adjusting the flow to either a trickle or a strong flow depending on what they want. Corvids score high on the Gf part of the CHC model, though it should be said that the Japanese crow in the article did not turn the faucet back off again, which might just be because they do not care if it keeps running.
When it comes to crystallized intelligence (Gc) and the memory-related Gsm and Glr abilities, corvids score pretty high as well. They have been reported to remember human faces, to learn from other crows by observing them, and are excellent at mimicking the sounds that other birds make. There is evidence that corvids and other avian dinosaur species (‘birds’) are capable of learning to understand human language, and even communicating with humans using these learned words.
The key here is whether the animal understands the meaning of the vocalization and what vocalizing it is meant to achieve when interacting with a human. Both parrots and crows show signs of being able to learn significant vocabularies of hundreds of words and conceivably a basic understanding of their meaning, or at least what they achieve when uttered, especially when it comes to food.
Whether non-human animals are capable of complex human speech remains a highly controversial topic, of course, though we are breathlessly awaiting the day that the first crow looks up at a human and tells the hairless monkey what they really think of them and their species as a whole.
The Bears
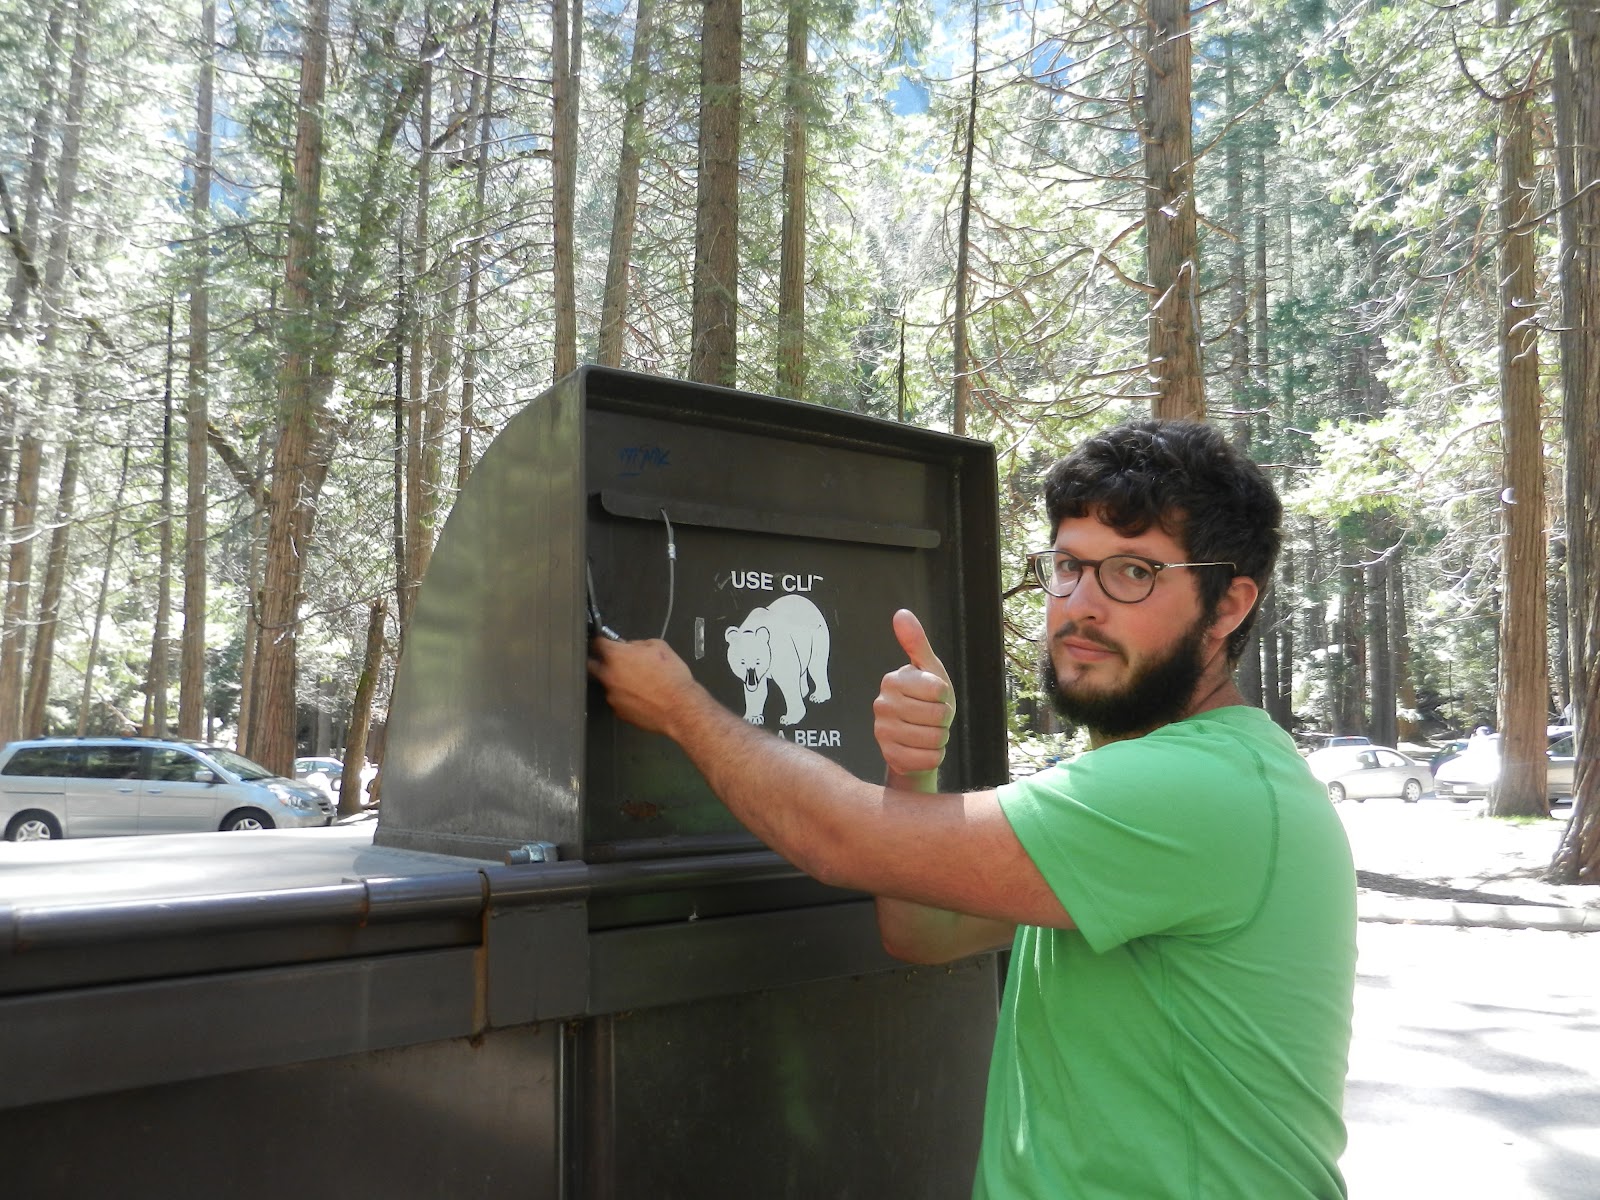
The bear-proof garbage bins at Yosemite National Park. (Credit: detourtravelblog)
Meanwhile there’s a veritable war of intellects going on in US National Parks between humans and bears, involving keeping the latter out of food lockers and trash bins while the humans begin to struggle the moment the bear-proof mechanism requires more than two hand motions. This sometimes escalates to the point where bears are culled when they defeat mechanisms using brute force.
Over the decades bears have learned that human food is easier to obtain and fills much better than all-natural food sources, yet humans are no longer willing to share. The result is an arms race where bears are more than happy to use any means necessary to obtain tasty food. Ergo we can put the Gf, Gc and memory-related scores for bears also at a level that suggests highly capable intellects, with a clear ability to learn, remember, and defeat obstacles through intellect. Sadly, the bear body doesn’t lend itself well to creating and using tools like a corvid can.
Despite the flaws of the CHC model and the weaknesses inherent in the associated IQ test scores, it does provide some rough idea of how these assessed capabilities are distributed across a population, leading to a distinct Bell curve for IQ scores among humans and conceivably for other species if we could test them. Effectively this means that there is likely significant overlap between the less intelligent humans and smarter non-human animals.
Although H. sapiens is undeniably an intelligent species, the reality is that it wasn’t some gods-gifted power, but rather an evolutionary quirk that it shares with many other lifeforms. This does however make it infinitely more likely that we can replicate it with a machine and/or computer system.
Making Machines Intelligent
Artificial Intelligence Projects for the Commodore 64, by Timothy J. O’Malley
The conclusion we have thus reached after assessing HI is that if we want to make machines intelligent, they need to acquire at least the Gf, Gc, Gsm and Glr capabilities, and at a level that puts them above that of a human toddler, or a raven if you wish.
Exactly how to do this has been the subject of much research and study the past millennia, with automatons (‘robots’) being one way to pour human intellect into a form that alleviates manual labor. Of course, this is effectively merely on par with creating tools, not an independent form of intelligence. For that we need to make machines capable of learning.
So far this has proved very difficult. What we are capable of so far is to condense existing knowledge that has been annotated by humans into a statistical model, with large language models (LLMs) as the pinnacle of the current AI hype bubble. These are effectively massively scaled up language models following the same basic architecture as those that hobbyists were playing with back in the 1980s on their home computers.
With that knowledge in mind, it’s not so surprising that LLMs do not even really register on the CHC model. In terms of Gf there’s not even a blip of reasoning, especially not inductively, but then you would not expect this from a statistical model.
As far as Gc is concerned, here the fundamental flaw of a statistical model is what it does not know. It cannot know what it doesn’t know, nor does it understand anything about what is stored in the weights of the statistical model. This is because it’s a statistical model that’s just as fixed in its functioning as an industrial robot. Chalk up another hard fail here.
Finally, although the context window of LLMs can be considered to be some kind of short-term memory, it is very limited in its functionality. Immediate recall of a series of elements may work depending on the front-end, but cognitive operations invariably fail, even very basic ones such as adding two numbers. This makes Gsm iffy at best, and more realistically a complete fail.
Finally, Glr should be a lot easier, as LLMs are statistical models that can compress immense amounts of data for easy recall. But this associative memory is an artefact of human annotation of training data, and is fixed at the time of training the model. After that, it does not remember outside of its context window, and its ability to associate text is limited to the previous statistical analysis of which words are most likely to occur in a sequence. This fact alone makes the entire Glr ability set a complete fail as well.
Piecemeal Abilities
Although an LLM is not intelligent by any measure and has no capacity to ever achieve intelligence, as a tool it’s still exceedingly useful. Technologies such as artificial neurons and large language models have enabled feats such as machine vision that can identify objects in a scene with an accuracy depending on the training data, and by training an LLM on very specific data sets the resulting model can be a helpful statistical tool, as it’s a statistical model.
These are all small fragments of what an intelligent creature is capable of, condensed into tool form. Much like hand tools, computers and robots, these are all tools that we humans have crafted to make certain tasks easier or possible. Like a corvid bending some wire into shape to open a lock or timing the dropping of nuts with a traffic light to safely scoop up fresh car-crushed nuts, the only intelligence so far is still found in our biological brains.
All of which may change as soon as we figure out a way to replicate abstract aspects such as reasoning and understanding, but that’s still a whole kettle of theoretical fish at this point in time, and the subject of future articles.
From Blog – Hackaday via this RSS feed
12
13
14
15
16
17
18
19
YSK that the offline OpenStreetMap application CoMaps is available on Linux via Flathub and macOS via the App Store
(lemmy.world)
I personally use OsmAnd on mobile (available exclusively on Android), but I've taken to using CoMaps on desktop. The menu UI on the right leaves something to be desired, and it's not nearly as powerful as OsmAnd; however, the map itself is rendered well and easy to navigate, the search and navigation functionalities work well, and map updates come frequently.
To me, it's the best desktop maps application provided OSM has decent coverage in your area. (If not, I could go on for thousands of words about why you, yes you, should contribute.)
Here's an example screenshot of a walking route between two nearby locations:

Context for those using Organic Maps: CoMaps is a fork of Organic made by former Organic contributors that has been active for over a year now. It's generally accepted as better than Organic. This is the open letter they wrote to Organic airing their grievances.
Why YSK: Offline maps are a great way to safeguard your privacy and don't require much storage space. Likewise, using OpenStreetMap is a great way to maintain digital sovereignty from giant corporations.
20
21
YSK about the Geo URI scheme, a standard way to link to a location so that users can open it in any map application or website
(thelemmy.club)
For each example in this post, I will be linking to the sea otter pools at the Vancouver aquarium. That location has the coordinates of 49.30063,-123.13149
To link to it, you would use 'geo:49.30063,-123.13149'.
Depending on your web browser, pasting that into the search bar might prompt you to select which map website you want to use to view that location. For me in Firefox, it asked me to pick between Google Maps and OpenStreetMaps. It's even more convenient on mobile, where it asks me which map app I want to open it with. Both CoMaps and Google Maps handled it correctly.
If you are writing a post or comment on Lemmy/Piefed/etc., you can place it in the second part of the markdown link format: [Sea Otter Pools](geo:49.30063,-123.13149). This would output like this: Sea Otter Pools
The linked OpenStreetMap wiki page has a good summary of how well various apps support this scheme. A lot of people here are active in the open source space, so please consider following up with the apps that are currently missing support or have partial support for this: https://wiki.openstreetmap.org/wiki/Geo_URI_scheme
EDIT: I forgot to mention, you can also use apps like this one to convert maps links between each other
https://github.com/jakubvalenta/GeoShare
https://f-droid.org/packages/page.ooooo.geoshare/
https://apt.izzysoft.de/fdroid/index/apk/page.ooooo.geoshare

22
23
I bought pumpkin pie spice because I couldn't find pumpkin spice. I made a pumpkin latte last night.
I made a simple recipe of oatmeal, pumpkin pie spice,milk and honey. It came out alright all the flavor was in certain chunks of the oatmeal. Need to brainstorm on how to distribute the flavor. Probably need to stir well
 This is what the outcome of my first pumpkin pie spice cereal

24
25
view more:
next ›