you are viewing a single comment's thread
view the rest of the comments
[–] 19 points 2 years ago (3 children)

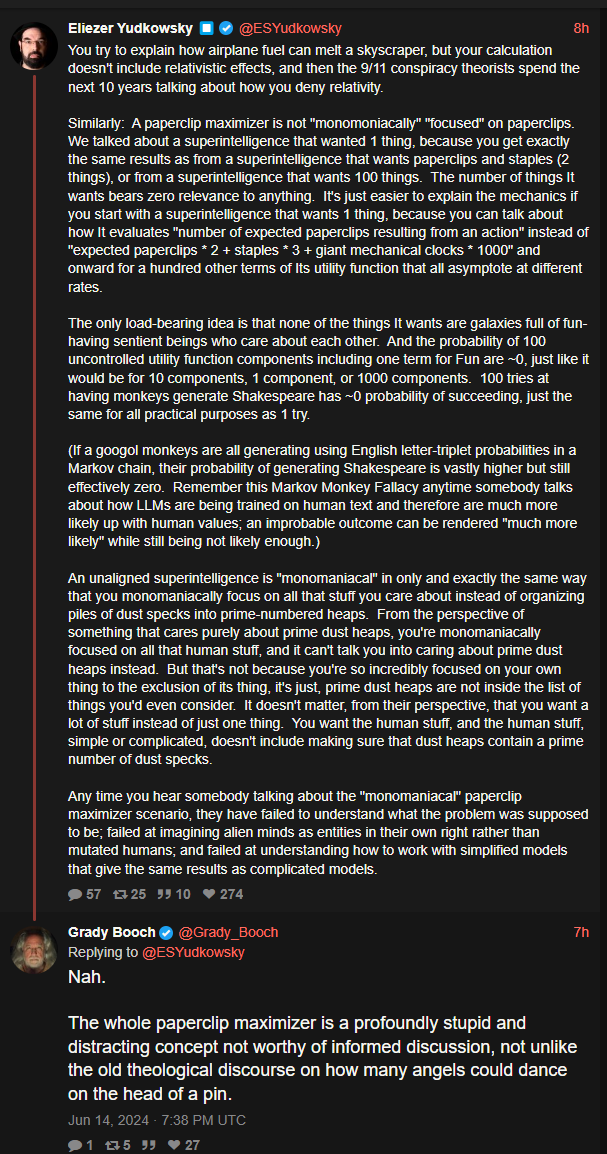
Before we accidentally make an AI capable of posing existential risk to human being safety, perhaps we should find out how to build effective safety measures first.

You make his position sound way more measured and responsible than it is.

His 'effective safety measures' are something like A) solve ethics B) hardcode the result into every AI, I.e. garbage philosophy meets garbage sci-fi.

  • source
  • parent
  • hideshow 3 child comments
  • [–] 8 points 2 years ago (2 children)

    This guy is going to be very upset when he realizes that there is no absolute morality.

  • source
  • parent
  • hideshow 2 child comments
  • [–] 9 points 2 years ago (1 child)

    A good chunk of philosophers do believe there are moral facts, but this is less useful for these purposes than one would think

  • source
  • parent
  • hideshow 1 child comment
  • [–] 8 points 2 years ago

    yeah it’s been absolutely hilarious to watch this play out in LLM space. so many prompt configurations and model deployments with so very many string-based rule inputs, meant to be configuring inviolable behaviour, that still get egregiously broken

    and afaict none of the dipshits have really seemed to internalise that just maybe their approach isn’t working

  • source
  • parent